In progress · 2026 – present
Fixation of Dominated Strategies in Group-Normalized Policy Gradient
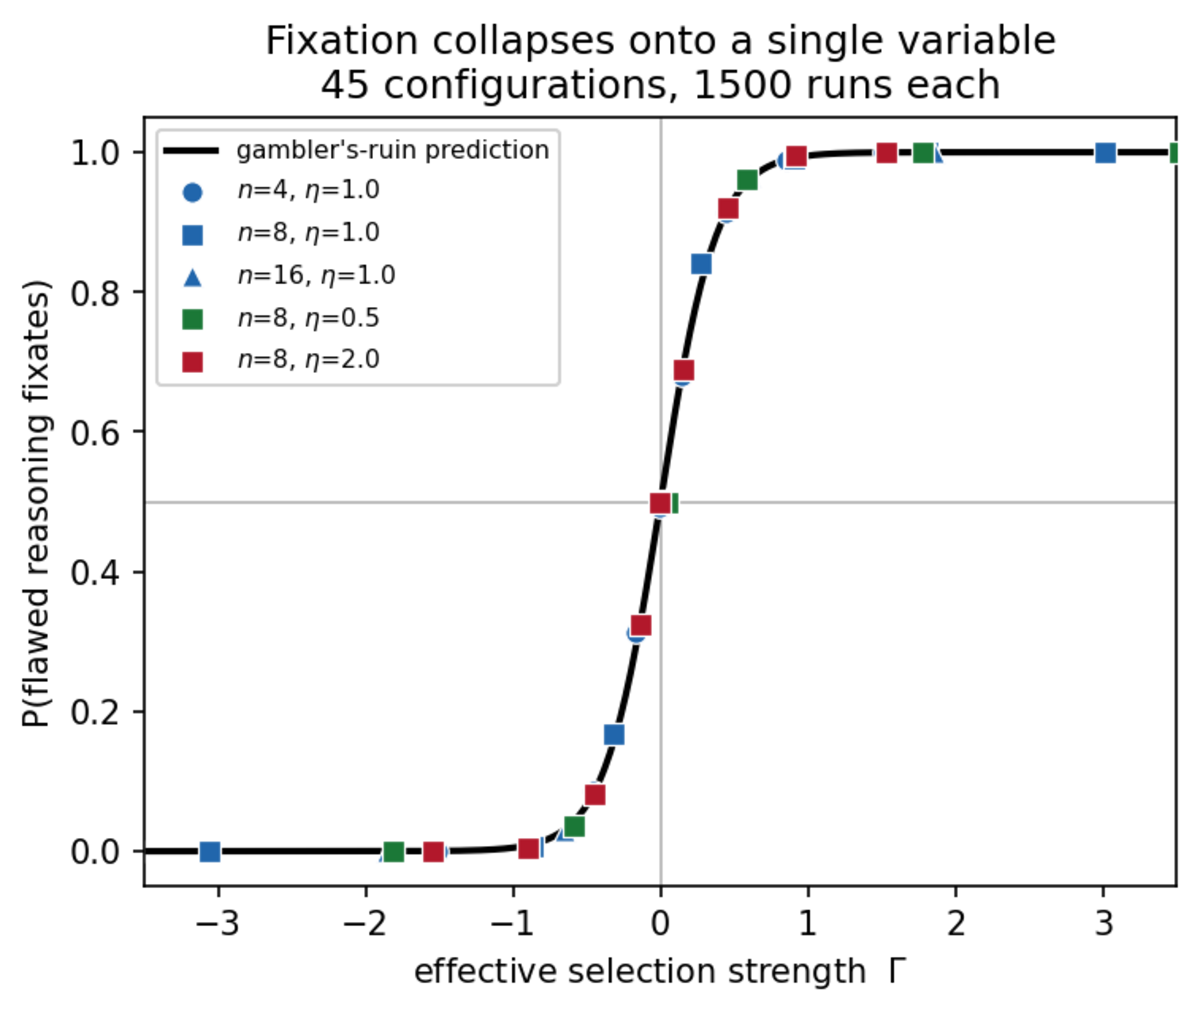
RL with verifiable rewards checks only the final answer, never the reasoning. I am showing that, because each update is so noisy, training can permanently lock in wrong reasoning even when correct reasoning is strictly better, and I derive the probability of this in closed form.